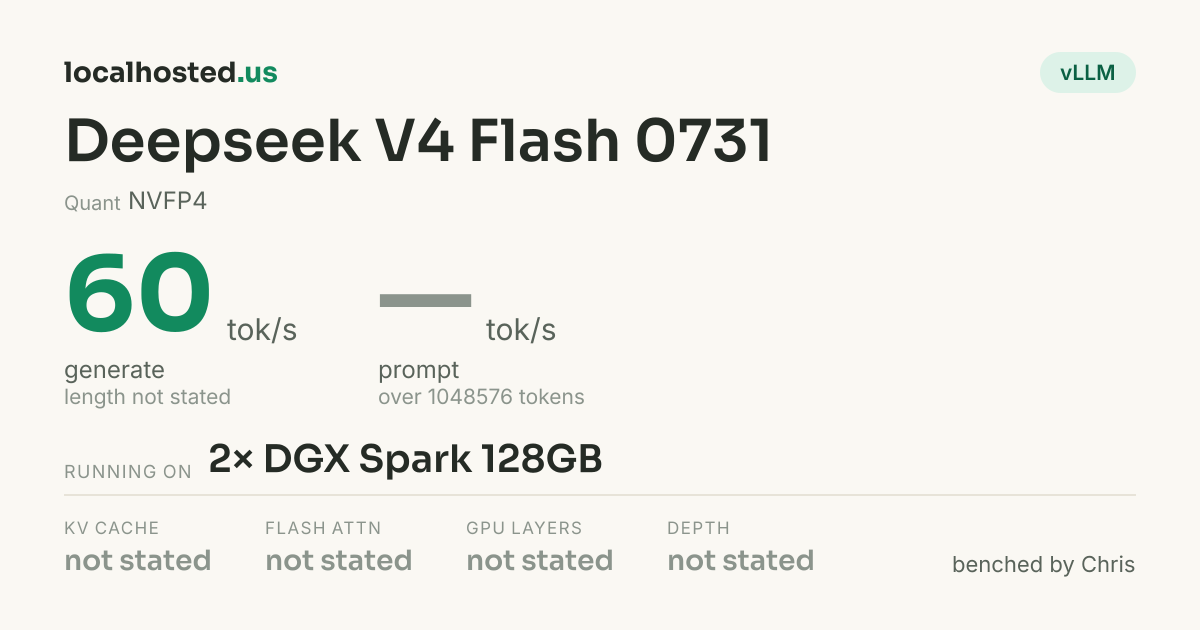
Posting the link is enough: X, Reddit and Discord turn it into the card automatically.
Deepseek V4 Flash 0731
Quant NVFP4
Generation
60tok/s
tokens written per second
Prompt
—
not measured
Model
- Quant
- NVFP4
How it ran
- Engine
- vLLM
This run does not say
- prompt speed — how long a long prompt takes before the first token
- KV cache type — a quantised cache changes both speed and memory
- how deep in the context — generation slows as the context fills
A run that answers all of these:
llama-bench -m model.gguf -p 2048 -n 512 -d 0,4096 -fa 1 -o json
Typed into the rig form rather than pasted, so nothing was recorded about how it was run.
Benched by Chris · Aug 26
The benchmark exactly as it was pasted
rig-run:2
Typed into the rig form, back when a rig could not be saved without a measurement.
There is no original engine output behind this one.

model:   Deepseek V4 Flash 0731
quant:   NVFP4
engine:  vLLM
decode:  60 tok/s
context: 1048576