Posting the link is enough: X, Reddit and Discord turn it into the card automatically.
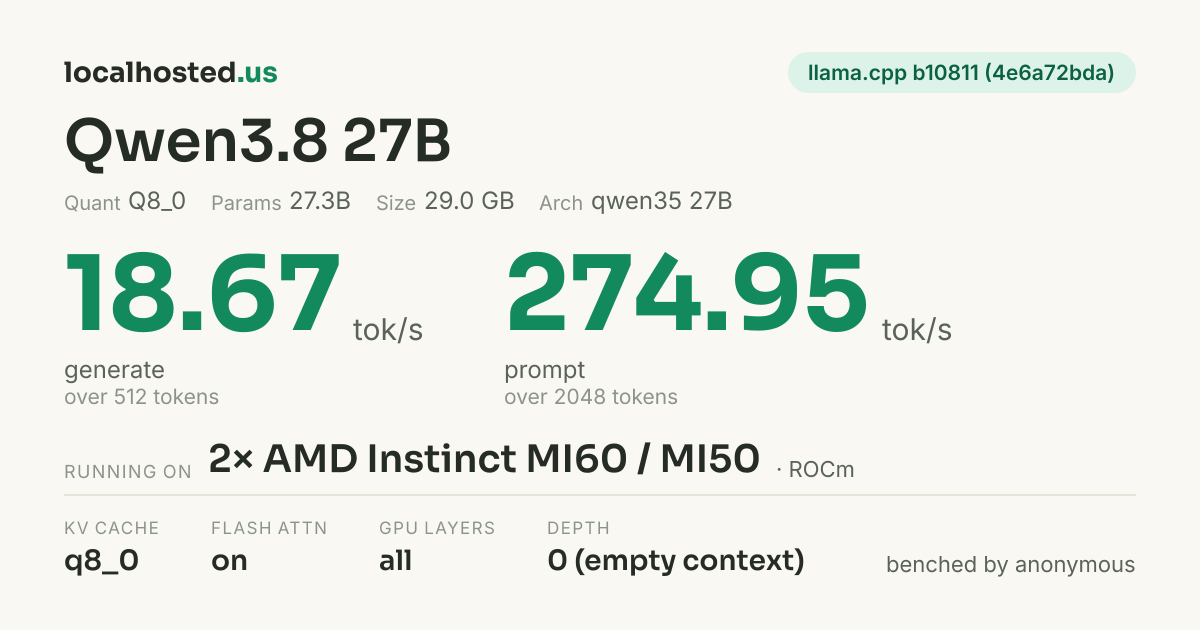
Qwen3.8 27B
Quant Q8_0Params 27.3BSize 29.0 GBArch qwen35 27B
on 2× AMD Instinct MI60 / MI50 · ROCm
Generation
18.67tok/s
over 512 tokens
Prompt
274.95tok/s
over 2048 tokens
Model
- Quant
- Q8_0
- Parameters
- 27.3B
- File size
- 29.0 GB
- Architecture
- qwen35 27B
- Variant
- sharpChatTemplate
- File
- Qwen3.8-27B-Q8_0-sharpChatTemplate.gguf
Machine
- Devices
- 2× AMD Instinct MI60 / MI50
- Backend
- ROCm
- CPU
- Intel(R) Xeon(R) CPU E5-1650 v3 @ 3.50GHz
How it ran
- Engine
- llama.cpp
- Build
- b10811 (4e6a72bda)
- KV cache
- q8_0
- Flash attention
- on
- GPU layers
- all
- Batch / ubatch
- 8192 / 2048
- Threads
- 6
- Split mode
- tensor
- Tensor split
- 1.00
- Context depth
- 0 (empty context)
Benched by anonymous · Sep 2 · run at 2026-09-02 09:14:16 UTC
The benchmark exactly as it was pasted
ggml_cuda_init: found 2 ROCm devices (Total VRAM: 65504 MiB):
  Device 0: AMD Instinct MI60 / MI50, gfx906:sramecc+:xnack- (0x906), VMM: no, Wave Size: 64, VRAM: 32752 MiB
  Device 1: AMD Instinct MI60 / MI50, gfx906:sramecc+:xnack- (0x906), VMM: no, Wave Size: 64, VRAM: 32752 MiB
[
[shexp-split] splitting shared experts across the TP group (LLAMA_SHEXP_SPLIT=0 to disable)
  {
    "build_commit": "4e6a72bda",
    "build_number": 10811,
    "cpu_info": "Intel(R) Xeon(R) CPU E5-1650 v3 @ 3.50GHz",
    "gpu_info": "AMD Instinct MI60 / MI50, AMD Instinct MI60 / MI50",
    "backends": "ROCm",
    "model_filename": "/models/Qwen3.8-27B-Q8_0-sharpChatTemplate.gguf",
    "model_type": "qwen35 27B Q8_0",
    "model_size": 29036089344,
    "model_n_params": 27320697856,
    "n_batch": 8192,
    "n_ubatch": 2048,
    "n_threads": 6,
    "cpu_mask": "0x0",
    "cpu_strict": false,
    "poll": 50,
    "type_k": "q8_0",
    "type_v": "q8_0",
    "n_gpu_layers": 999,
    "n_cpu_moe": 0,
    "split_mode": "tensor",
    "tensor_parallel_size": 0,
    "main_gpu": 0,
    "no_kv_offload": false,
    "flash_attn": 1,
    "devices": "auto",
    "tensor_split": "1.00",
    "tensor_buft_overrides": "none",
    "load_mode": "dio",
    "lazy_mode": "auto",
    "embeddings": false,
    "no_op_offload": 0,
    "no_host": false,
    "no_repack": false,
    "fit_target": 0,
    "fit_min_ctx": 0,
    "n_prompt": 2048,
    "n_gen": 0,
    "n_depth": 0,
    "test_time": "2026-09-02T09:14:00Z",
    "avg_ns": 7448695478,
    "stddev_ns": 0,
    "avg_ts": 274.947473,
    "stddev_ts": 0.000000,
    "samples_ns": [ 7448695478 ],
    "samples_ts": [ 274.947 ]
  },
  {
    "build_commit": "4e6a72bda",
    "build_number": 10811,
    "cpu_info": "Intel(R) Xeon(R) CPU E5-1650 v3 @ 3.50GHz",
    "gpu_info": "AMD Instinct MI60 / MI50, AMD Instinct MI60 / MI50",
    "backends": "ROCm",
    "model_filename": "/models/Qwen3.8-27B-Q8_0-sharpChatTemplate.gguf",
    "model_type": "qwen35 27B Q8_0",
    "model_size": 29036089344,
    "model_n_params": 27320697856,
    "n_batch": 8192,
    "n_ubatch": 2048,
    "n_threads": 6,
    "cpu_mask": "0x0",
    "cpu_strict": false,
    "poll": 50,
    "type_k": "q8_0",
    "type_v": "q8_0",
    "n_gpu_layers": 999,
    "n_cpu_moe": 0,
    "split_mode": "tensor",
    "tensor_parallel_size": 0,
    "main_gpu": 0,
    "no_kv_offload": false,
    "flash_attn": 1,
    "devices": "auto",
    "tensor_split": "1.00",
    "tensor_buft_overrides": "none",
    "load_mode": "dio",
    "lazy_mode": "auto",
    "embeddings": false,
    "no_op_offload": 0,
    "no_host": false,
    "no_repack": false,
    "fit_target": 0,
    "fit_min_ctx": 0,
    "n_prompt": 0,
    "n_gen": 512,
    "n_depth": 0,
    "test_time": "2026-09-02T09:14:16Z",
    "avg_ns": 27428188867,
    "stddev_ns": 0,
    "avg_ts": 18.666927,
    "stddev_ts": 0.000000,
    "samples_ns": [ 27428188867 ],
    "samples_ts": [ 18.6669 ]
  },
  {
    "build_commit": "4e6a72bda",
    "build_number": 10811,